Setting up model parameters
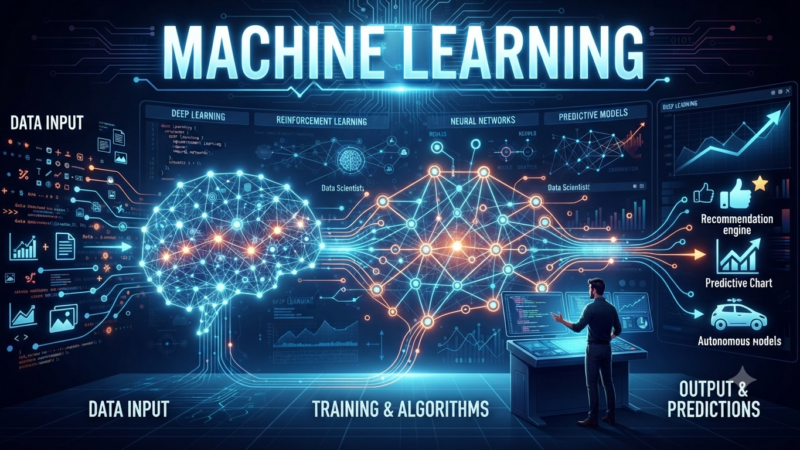
You can manually set the matching function y^=f(x) (called a predictive or forecast function) that would produce predictions of the response y^based on known features, but this is often difficult to do due to the diversity of objects and complex dependencies between features and response. Therefore, in supervised machine learning, the correspondence between features and response is sought in a certain class of functions.fw(x), parameterized by a vector of parameters w, which are selected based on a training sample consisting of N objects:
(x1,y1),(x2,y2),...(xN,yN).
The model parameters will also be called model weights .
For example, a class of functions might be the set of all constant predictions:

or consist of all linear functions of the features:

There are also more complex families of functions, which will be discussed in the following chapters.
To select the best one from a family of functions (which is equivalent to selecting a specific vector of parameters w^), it is necessary to numerically formalize which forecasts we will consider good and which bad. For this, a loss function is defined, L(y, y^), depending on the true value of the responseyand predictedy^The higher the value of the loss function, the worse the forecast is considered.
Basic loss functions in a regression problem
Let’s consider the main loss functions in a regression problem:
| Name | formula |
|---|---|
| squared error (L2 loss) | (y^–y)2 |
| absolute error (L1 loss) | ∣y^–y∣ |
A smooth combination of both loss functions, called the Huber function (smooth L1 loss), is also widely used:
{0.5⋅x2,β⋅( ∣ x ∣–0.5⋅β ) ,if ∣ x ∣<β ,if ∣ x ∣≥β ,
In the latter caseβ>0– a hyperparameter that specifies the region of a quadratic dependence that extends linearly beyond this region, preserving the continuity of the function itself and the continuity of its derivative.
Being smooth, this function is convenient for optimization, but at the same time is as robust to atypical observations as the error module.
Example of losses for classification
For a classification problem, the simplest loss function is the error indicator, calculated using the formulaI{y^≠y}, where I {condition} is the indicator function. I {condition} returns 1 if the condition is met and 0 otherwise. Looking ahead, we should note that in practice, this function cannot be used for tuning models, since it is not differentiable. Therefore, other loss functions are used for classification, which will be discussed below.
Win function
The loss function should not be confused with the score function S(y^,y), which is also common in machine learning. For worse predictions, the loss function should take higher values, while the gain function should take lower values.
For example, for classification, the winning function is the indicator of the correct guess of the classI{y^=y}.
Theoretical and empirical risk
To configure the model parameters, traditionally, one wants to minimize the expected losses on new objects coming from some probability distribution, called theoretical risk:
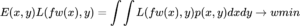
In practice, this value is uncalculable due to the fact that we do not have information about the theoretical distribution of objects.p(x,y) but we only know a limited training sample(x1,y1),(x2,y2),...(xN,yN). Therefore, in practice, the parameters are found by minimizing the empirical risk L(w), which is a sample estimate of the theoretical risk based on the training sample:

Parameter estimationw^is defined as the empirical risk minimizer:
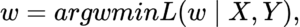
WhereX∈RN×D– the “object-feature” matrix, also called the feature matrix. The rows of this matrix correspond to D-dimensional feature vectors for each of N objects of the training sample, andY∈RN– the vector of responses that we want to learn to predict based on the features.

A model with tuned parameters is also called a forecasting algorithm.
Model parameters should not be confused with hyperparameters , which are not configured based on the training sample, but are specified by the user or selected based on a separate sample, called the validation sample.
Explore More IT Terms
#
- Using an integrating factor
- Equations in total differentials
- Bernoulli's equation
- Linear differential equations of the first order
- 10 Mixed C++ Challenges to Test Your Skills
- 11 Tricky Non-Technical Questions to Ask in a Recruiting Interview
- 50 Terms Every Programmer Should Know
- 52 Java Thread Interview Questions
- 7 Levels of Using the Zip Function in Python
- 7 Python Code Bugs You Need to Fix
- 70+ Free Resources for Learning Programming
A
- A Comprehensive Guide to HTML and CSS
- A Comprehensive Guide to MODX CMS
- A computer science question tests your ability to work with IP addresses and network masks
- A Guide to SQL Query Formatting for Beginners
- A/B testing
- Abstract Data Type (ADT)
- AES Encryption Algorithm: How It Works and Where It's Used
- Agile
- Algorithm
- Algorithm Analysis
- Algorithm Complexity-Key Points
- Algorithm complexity: deep parsing O(log n)
- Algorithm vs. Program
- Algorithms and Data Structures in C#
- An overview of the C # programming language
- An overview of the Python programming language
- Anaconda Python
- Analysis of graphs and adjacency matrices question
- Android
- Android App Bundle
- Android SDK
- Angular
- Ansible
- Apache
- Apache Airflow
- Apache Kafka
- Apache Tomcat
- App Store
- AppCode
- Applications of microcontrollers: From simple circuits in electronics to complex systems
- Applications of the derivative
- Arduino: How to Program It: Basics for Beginners
- Array-based stack
- ArrayList
- ASCII
- ASP.NET
- Assembly Language Lessons
B
C
- C++ Lessons
- Cache
- Calculating Memory Capacity
- Character sets and encodings
- Characteristics of a good Algorithm
- Circular singly linked list
- Coding Tests with Answers
- Combinational Circuits Solved Questions
- Compiler
- Complexity of algorithms-Tutorial
- Computer Science Fundamentals Test with Answers (47 questions)
- Computer science tests with answers (More than 100 Questions)
- Constants
- Creating a Table in HTML
- Creating Forms in HTML
- Creating Lists
- Cybernetics and informatics
- Cycles
D
- Data Analytics: applications of data analysis in companies
- Data Engineer - Who is it, what does a data engineer do, and an overview of the profession
- Data modeling: what it is, types, and process steps.
- Data preprocessing: a complete guide for beginners and professionals.
- Data structure
- Data Structures and Algorithms (DSA)
- Data types vs. Data structures
- Database Tests with Answers
- Deep Learning
- Defining Aliases
- Defining Arrays
- Deque
- Detailed articles and tutorials on PHP
- Developing a Website from Scratch
- Differential Equations
- Differentiation of functions
- Digital data: understand the importance of this asset for businesses.
- Double integrals
- Doubly linked lists
- DSA Tutorial
E
F
G
H
- Handling errors and exceptions
- Heads or Tails? How Probability Theory Is Used in IT
- History of the development of computer science
- Homogeneous equations
- Homogeneous vs. non-homogeneous structures
- How to convert numbers between binary, octal, and hexadecimal number systems
- How to effectively organize your workflow
- How to Learn Java: Tips for Beginner Developers
- How to Learn PHP: A Beginner's Guide
- How to Use S3 Storage in Kubernetes with CSI
- HTML
- HTML and CSS: Definition, Application, and Operating Principles
- HTML and CSS. Layout from Scratch: What to Learn, Where to Learn, and How Long Will It Take?
- HTML Frame Structure
- HTML Link Formatting
- HTML Quizzes with Answers
I
- if..else construction
- Infinite sequences and series
- Information properties
- Inheritance in Java: A Complete Guide to Principles and Implementation
- Inserting an Image
- Integration of functions
- Interactive Python Tutorial – Learn Programming from Scratch
- Interpreter
- Interview Problem: Finding a Deleted Element in O(N)
- Interview Scare: The FizzBuzz Challenge
- Introduction to C++
- Introduction to Machine Learning
- Introduction to Machine Learning with Python
- Introduction to Networking | Network Fundamentals Part 1
- Introduction to Number Systems (Binary, Octal, Hexadecimal) | Math for CS Foundations #1
- IT Specialist Resume (CV)
J
K
L
M
- Machine Learning
- Machine Learning Basic Tool: NumPy
- Machine Learning Basic Tool: Pandas
- Machine Learning Basics
- Machine Learning Mathematics
- Machine Learning with Python
- Mathematics for programmers: what is really needed?
- MD5 encryption algorithm: What is it and why is it needed?
- Microcontroller and Microprocessor - what's the difference?
- ML Engineer: Who They Are, What They Do, How Much They Earn, and How to Become a Neural Network Specialist
- Monte Carlo Simulation: How It Works and What It's For
O
P
- PHP lessons
- Private DNS server and its configuration
- Program code
- Programmer's Dictionary
- Programming
- Programming with pseudocode
- Python Code Formatting Guide: PEP8
- Python for data analysis: how to do it and main libraries
- Python Lessons
- Python Superstar: 5 Ways to Use the * Operator
- Python vs. Julia: Should You Replace Python with Julia?
Q
R
S
- Setting up model parameters
- SFML Graphics Library Tutorials
- Sorting Algorithms in Programming: Types, Descriptions, and Comparisons
- SQL commands: see what they are, what the main ones are + examples
- SQL Interview Questions and Tasks
- SQL Lessons
- SQL Stored Procedures
- SQL Syntactic Sugar: The COALESCE Function
- Stack
- Start in analytics: Python or R
- Static vs. dynamic data structures
- Statistical analysis: importance for decision making.
- String formatting in Python
- Structure of computer science
- Supervised learning
- Swift Lessons
- switch/match construct
- Syntax
T
- Terms in programming
- Text and paragraph formatting tags
- The Complete Guide to Bootstrap
- The Complete Guide to JavaScript
- The concept of information and its transmission
- The Future of Python: Key Trends and Insights from Global Researc
- The Infrastructure of Code: A Complete Guide to Repositories for Languages, Frameworks, and Compilers
- The pip package manager in Python
- The role of informatization in the development of society
- Transfers
- Tricky Java Questions Often Asked in Interviews
- Tutorials / Articles
- TypeScript: What It Is and Why Developers Need It
W
- What are databases, and why do they need DBMS and SQL?
- What do Linux distributions consist of?
- What is .NET and what is it used for?
- What is a data structure?
- What is a GPU in a computer, in simple terms?
- What is a quantum computer: 100,500 problems in one second
- What Is an Algorithm?
- What is Arduino: How it Works and the Platform's Capabilities
- What is Big Data? Introduction, Types, Characteristics, and Examples
- What is FizzBuzz Challenge?
- What is Golang and what is it used for?
- What is Haskell and what is it used for?
- What is Kotlin and what is it used for?
- What is Linux? The History of Linux
- What is machine learning, and how does it work?
- What is Power BI: everything about the data analytics software
- What is recursion, recursive and iterative process in programming?
- What is the C++ programming language?
- What is the OSI Model: A Complete Explanation of the Seven Layers and Their Role in Networking
- What's the difference between x86 and ARM processors?
- Where to start learning the C programming language?
- Which Linux distribution should you choose? A Linux distribution overview